Publications
* Equal contribution.
2026
- Workshop ECCV EmergingADPictura: Perspective-View Self-Play at Scale for DrivingYuan Yin, Elias Ramzi, Marc Lafon, Valentin Charraut, Victor Bares, Yihong Xu, Éloi Zablocki, Alexandre Boulch, Thibault Buhet, Andrei Bursuc, and Matthieu CordIn ECCV 2026 Workshop on Emerging Behaviors in Embodied AI for Achieving Robust Autonomy, Sep 2026Oral presentation
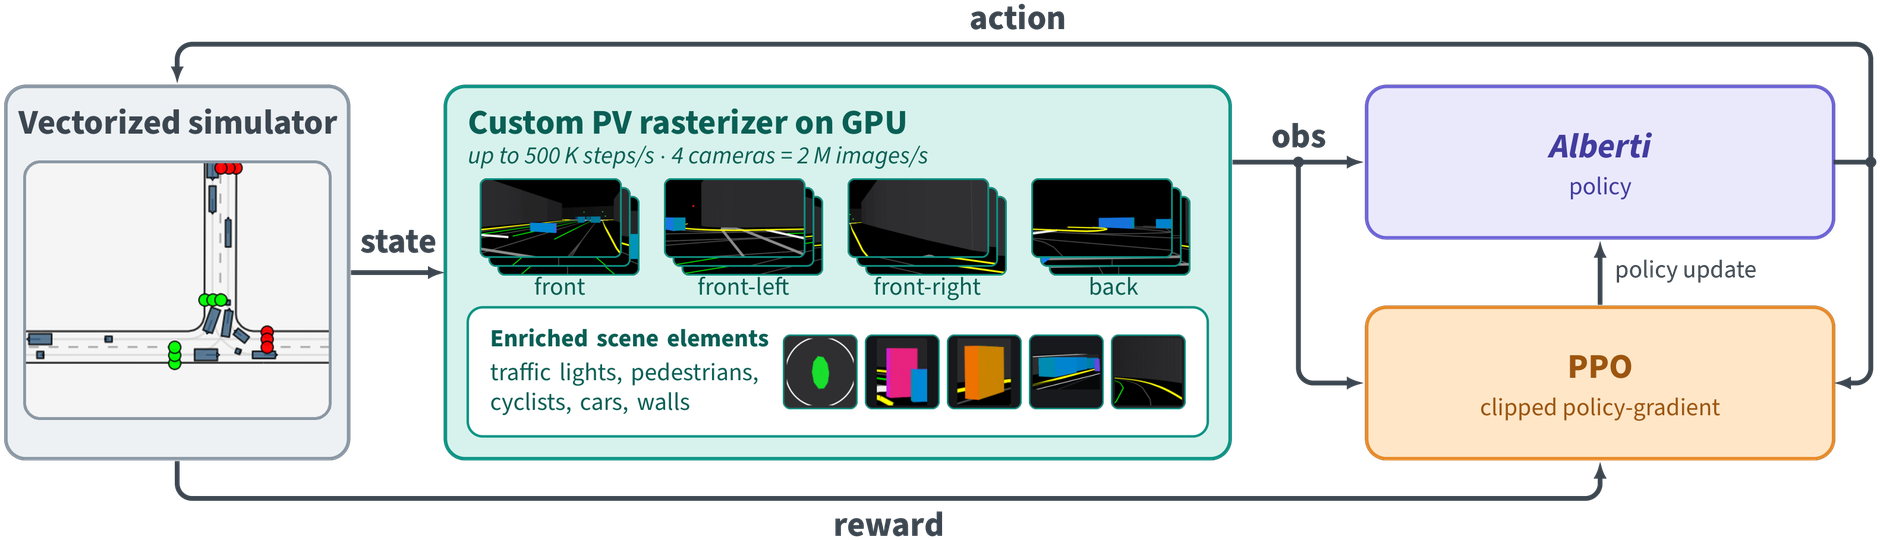
Self-play in simulation produces robust driving policies at scale. Demonstrations of such behavior have been made using privileged vectorized observations such as exact poses and velocities, even for occluded agents. This assumes that perception is solved and introduces a representation gap with the partial observation of a deployed agent driving from the perspective view of egocentric cameras. A common fix, distilling the privileged policy into a camera-input student, leaves the student imitating decisions its own view cannot justify. Instead, we establish perspective-view self-play as a practical training regime. We introduce Pictura, a GPU-accelerated multi-agent driving simulator that renders each agent’s egocentric view at every step, mitigating the representation gap at its source. Pictura sustains up to 500K agent-steps/s (2M images/s) on a single H100. Using Pictura, we train Alberti by self-play with plain PPO. It is the first large-scale driving self-play policy trained directly from perspective images, without privileged observations. Training spans 50B agent steps for 35M km of driving. It approaches the driving performance of its privileged vectorized counterpart, and transfers zero-shot to Waymo Open Motion Dataset layouts re-rendered in Pictura, where it outperforms privileged vectorized agents.
@inproceedings{yin2026pictura, title = {Pictura: Perspective-View Self-Play at Scale for Driving}, author = {Yin, Yuan and Ramzi, Elias and Lafon, Marc and Charraut, Valentin and Bares, Victor and Xu, Yihong and Zablocki, Éloi and Boulch, Alexandre and Buhet, Thibault and Bursuc, Andrei and Cord, Matthieu}, booktitle = {ECCV 2026 Workshop on Emerging Behaviors in Embodied AI for Achieving Robust Autonomy}, note = {Oral presentation}, year = {2026}, month = sep, } - PreprintTOAD: Test-Time Trajectory Optimization for Autonomous DrivingYihong Xu, Éloi Zablocki, Yuan Yin, Elias Ramzi, Ellington Kirby, Alexandre Boulch, and Matthieu CordJun 2026

End-to-end planners for autonomous driving typically generate a set of candidate trajectories, score each one, and return the highest-scoring candidate. However, the scorer is applied only after the proposals are generated and cannot influence the set of trajectories: a weak set of candidates limits planning performance regardless of the scorer’s quality. We instead treat the scorer as a learned trajectory-level reward function and search for trajectories that maximize it. Our method, TOAD, runs the Cross-Entropy Method at test time, warm-started from the planner’s proposals. It requires no retraining and is plug-and-play for existing planners. Across six base planners, TOAD improves results on NAVSIM-v1 (94.7 PDMS), NAVSIM-v2 (56.3 EPDMS), and the closed-loop HUGSIM benchmark.
@misc{xu2026toad, title = {TOAD: Test-Time Trajectory Optimization for Autonomous Driving}, author = {Xu, Yihong and Zablocki, Éloi and Yin, Yuan and Ramzi, Elias and Kirby, Ellington and Boulch, Alexandre and Cord, Matthieu}, year = {2026}, month = jun, } - Conference CVPRDriving on RegistersEllington Kirby, Alexandre Boulch, Yihong Xu, Yuan Yin, Gilles Puy, Éloi Zablocki, Andrei Bursuc, Spyros Gidaris, Renaud Marlet, Florent Bartoccioni, Anh-Quan Cao, Nermin Samet, Tuan-Hung Vu, and Matthieu CordIn Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition, Jun 2026
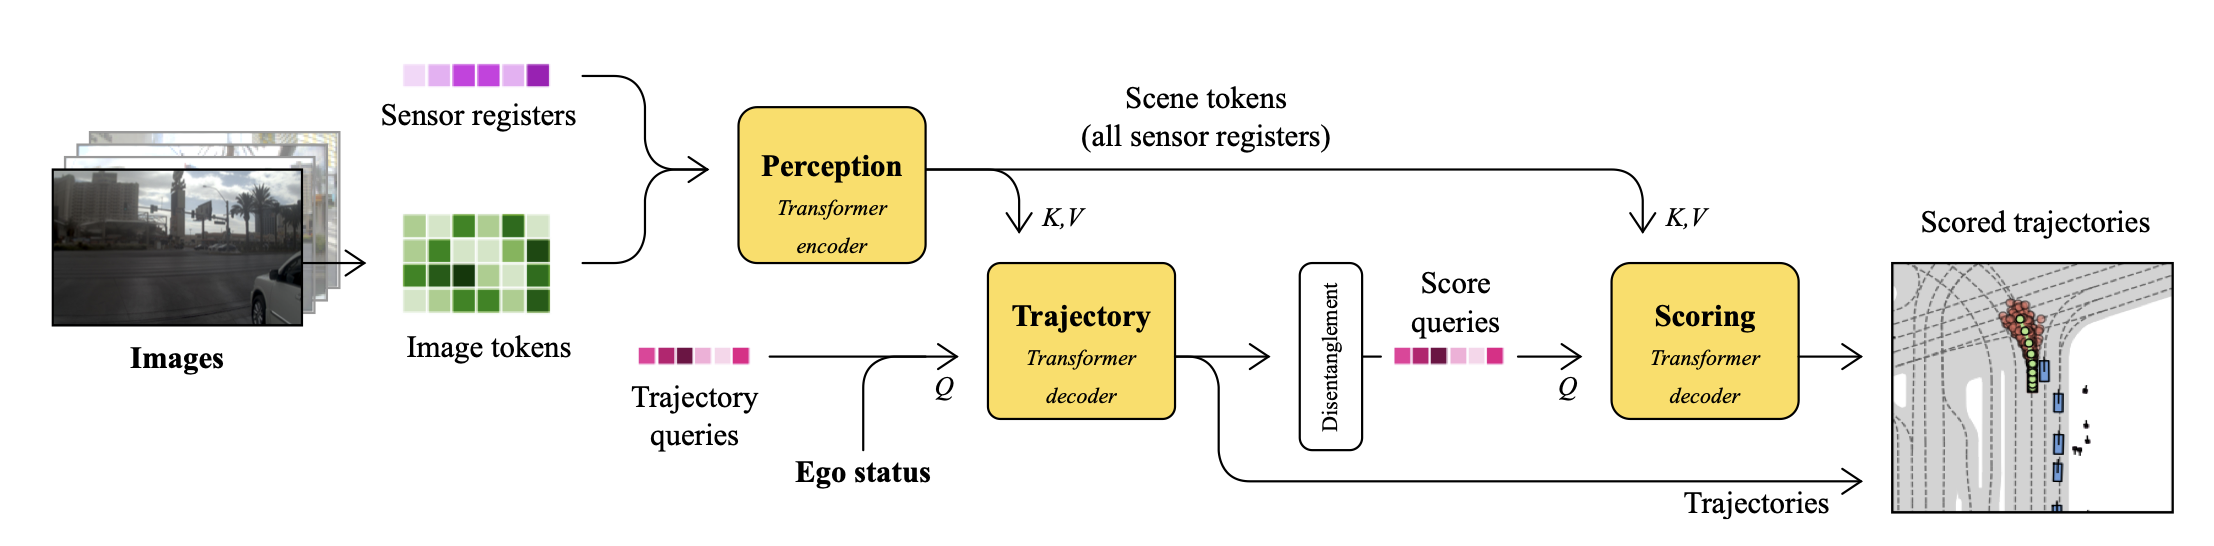
We present DrivoR, a simple and efficient transformer-based architecture for end-to-end autonomous driving. Our approach builds on pretrained Vision Transformers (ViTs) and introduces camera-aware register tokens that compress multi-camera features into a compact scene representation, significantly reducing downstream computation without sacrificing accuracy. These tokens drive two lightweight transformer decoders that generate and then score candidate trajectories. The scoring decoder learns to mimic an oracle and predicts interpretable sub-scores representing aspects such as safety, comfort, and efficiency, enabling behavior-conditioned driving at inference. Despite its minimal design, DrivoR outperforms or matches strong contemporary baselines across NAVSIM-v1, NAVSIM-v2, and the photorealistic closed-loop HUGSIM benchmark. Our results show that a pure-transformer architecture, combined with targeted token compression, is sufficient for accurate, efficient, and adaptive end-to-end driving. Code and checkpoints will be made available.
@inproceedings{kirby2026drivingregisters, title = {Driving on Registers}, author = {Kirby, Ellington and Boulch, Alexandre and Xu, Yihong and Yin, Yuan and Puy, Gilles and Zablocki, Éloi and Bursuc, Andrei and Gidaris, Spyros and Marlet, Renaud and Bartoccioni, Florent and Cao, Anh-Quan and Samet, Nermin and Vu, Tuan-Hung and Cord, Matthieu}, year = {2026}, month = jun, booktitle = {Proceedings of the IEEE/CVF Conference on Computer Vision and Pattern Recognition}, } - Conference ICRAPPT: Pre-Training with Pseudo-Labeled Trajectories for Motion ForecastingIn The 2026 IEEE International Conference on Robotics and Automation, Jan 2026
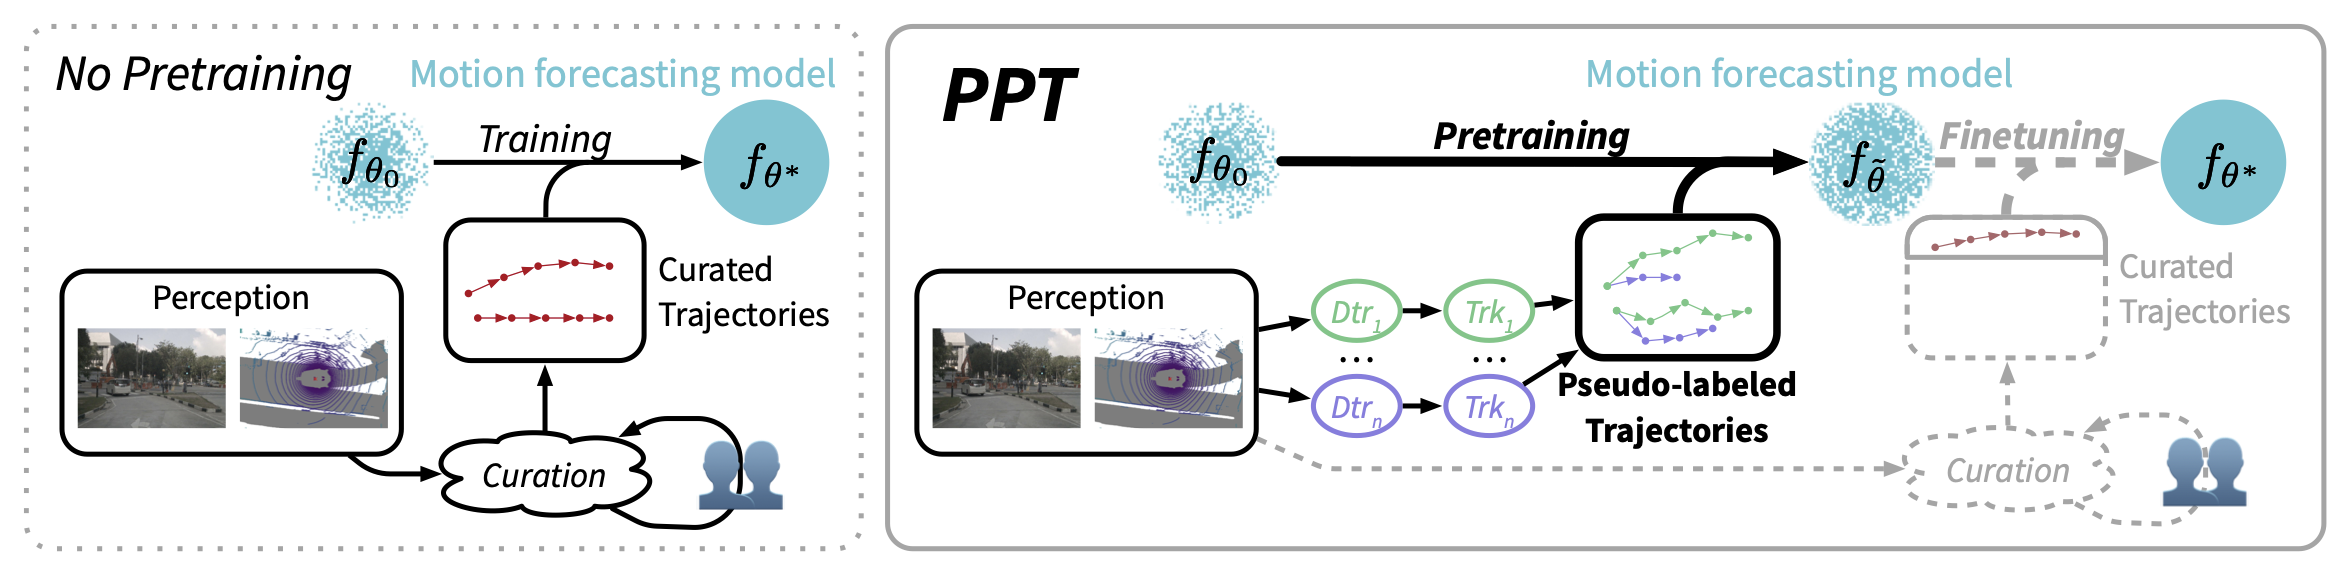
Motion forecasting (MF) for autonomous driving aims at anticipating trajectories of surrounding agents in complex urban scenarios. In this work, we investigate a mixed strategy in MF training that first pre-train motion forecasters on pseudo-labeled data, then fine-tune them on annotated data. To obtain pseudo-labeled trajectories, we propose a simple pipeline that leverages off-the-shelf single-frame 3D object detectors and non-learning trackers. The whole pre-training strategy including pseudo-labeling is coined as PPT. Our extensive experiments demonstrate that: (1) combining PPT with supervised fine-tuning on annotated data achieves superior performance on diverse testbeds, especially under annotation-efficient regimes, (2) scaling up to multiple datasets improves the previous state-of-the-art and (3) PPT helps enhance cross-dataset generalization. Our findings showcase PPT as a promising pre-training solution for robust motion forecasting in diverse autonomous driving contexts.
@inproceedings{xu2026ppt,
  title = {PPT: Pre-Training with Pseudo-Labeled Trajectories for Motion Forecasting},
  author = {Xu, Yihong and Yin, Yuan and Vu, Tuan-Hung and Boulch, Alexandre and Zablocki, Éloi and Cord, Matthieu},
  year = {2026},
  month = jan,
  booktitle = {The 2026 IEEE International Conference on Robotics and Automation},
}


2025
- IPA: An Information-Reconstructive Input Projection Framework for Efficient Foundation Model AdaptationTransactions on Machine Learning Research, Sep 2025
IPA received the Best Paper Award at NeurIPS 2025 CCFM Workshop.
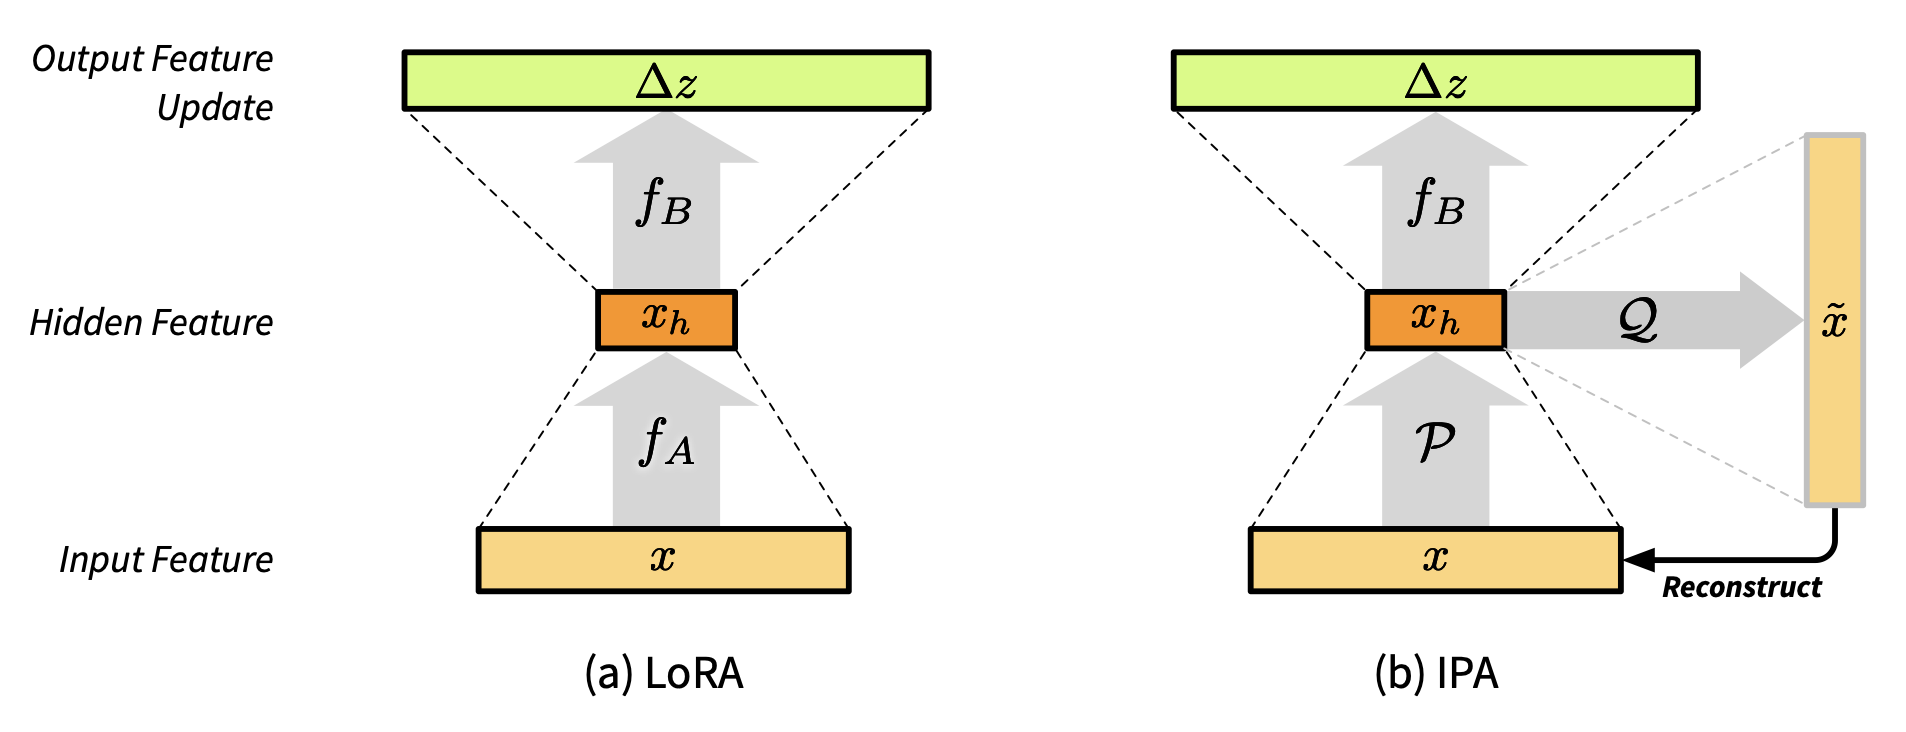
Parameter-efficient fine-tuning (PEFT) methods, such as LoRA, reduce adaptation cost by injecting low-rank updates into pretrained weights. However, LoRA’s down-projection is randomly initialized and data-agnostic, discarding potentially useful information. Prior analyses show that this projection changes little during training, while the up-projection carries most of the adaptation, making the random input compression a performance bottleneck. We propose IPA, a feature-aware projection framework that explicitly preserves information in the reduced hidden space. In the linear case, we instantiate IPA with algorithms approximating top principal components, enabling efficient projector pretraining with negligible inference overhead. Across language and vision benchmarks, IPA consistently improves over LoRA and DoRA, achieving on average 1.5 points higher accuracy on commonsense reasoning and 2.3 points on VTAB-1k, while matching full LoRA performance with roughly half the trainable parameters when the projection is frozen.
@article{yin2025ipainformationpreservinginputprojection, title = {IPA: An Information-Reconstructive Input Projection Framework for Efficient Foundation Model Adaptation}, author = {Yin, Yuan and Venkataramanan, Shashanka and Vu, Tuan-Hung and Bursuc, Andrei and Cord, Matthieu}, year = {2025}, month = sep, journal = {Transactions on Machine Learning Research}, } - Conference ICLRLearning a Neural Solver for Parametric PDE to Enhance Physics-Informed MethodsLise Le Boudec, Emmanuel de Bézenac, Louis Serrano, Ramón Daniel Regueiro Espiño, Yuan Yin, and Patrick GallinariIn The Thirteenth International Conference on Learning Representations, May 2025
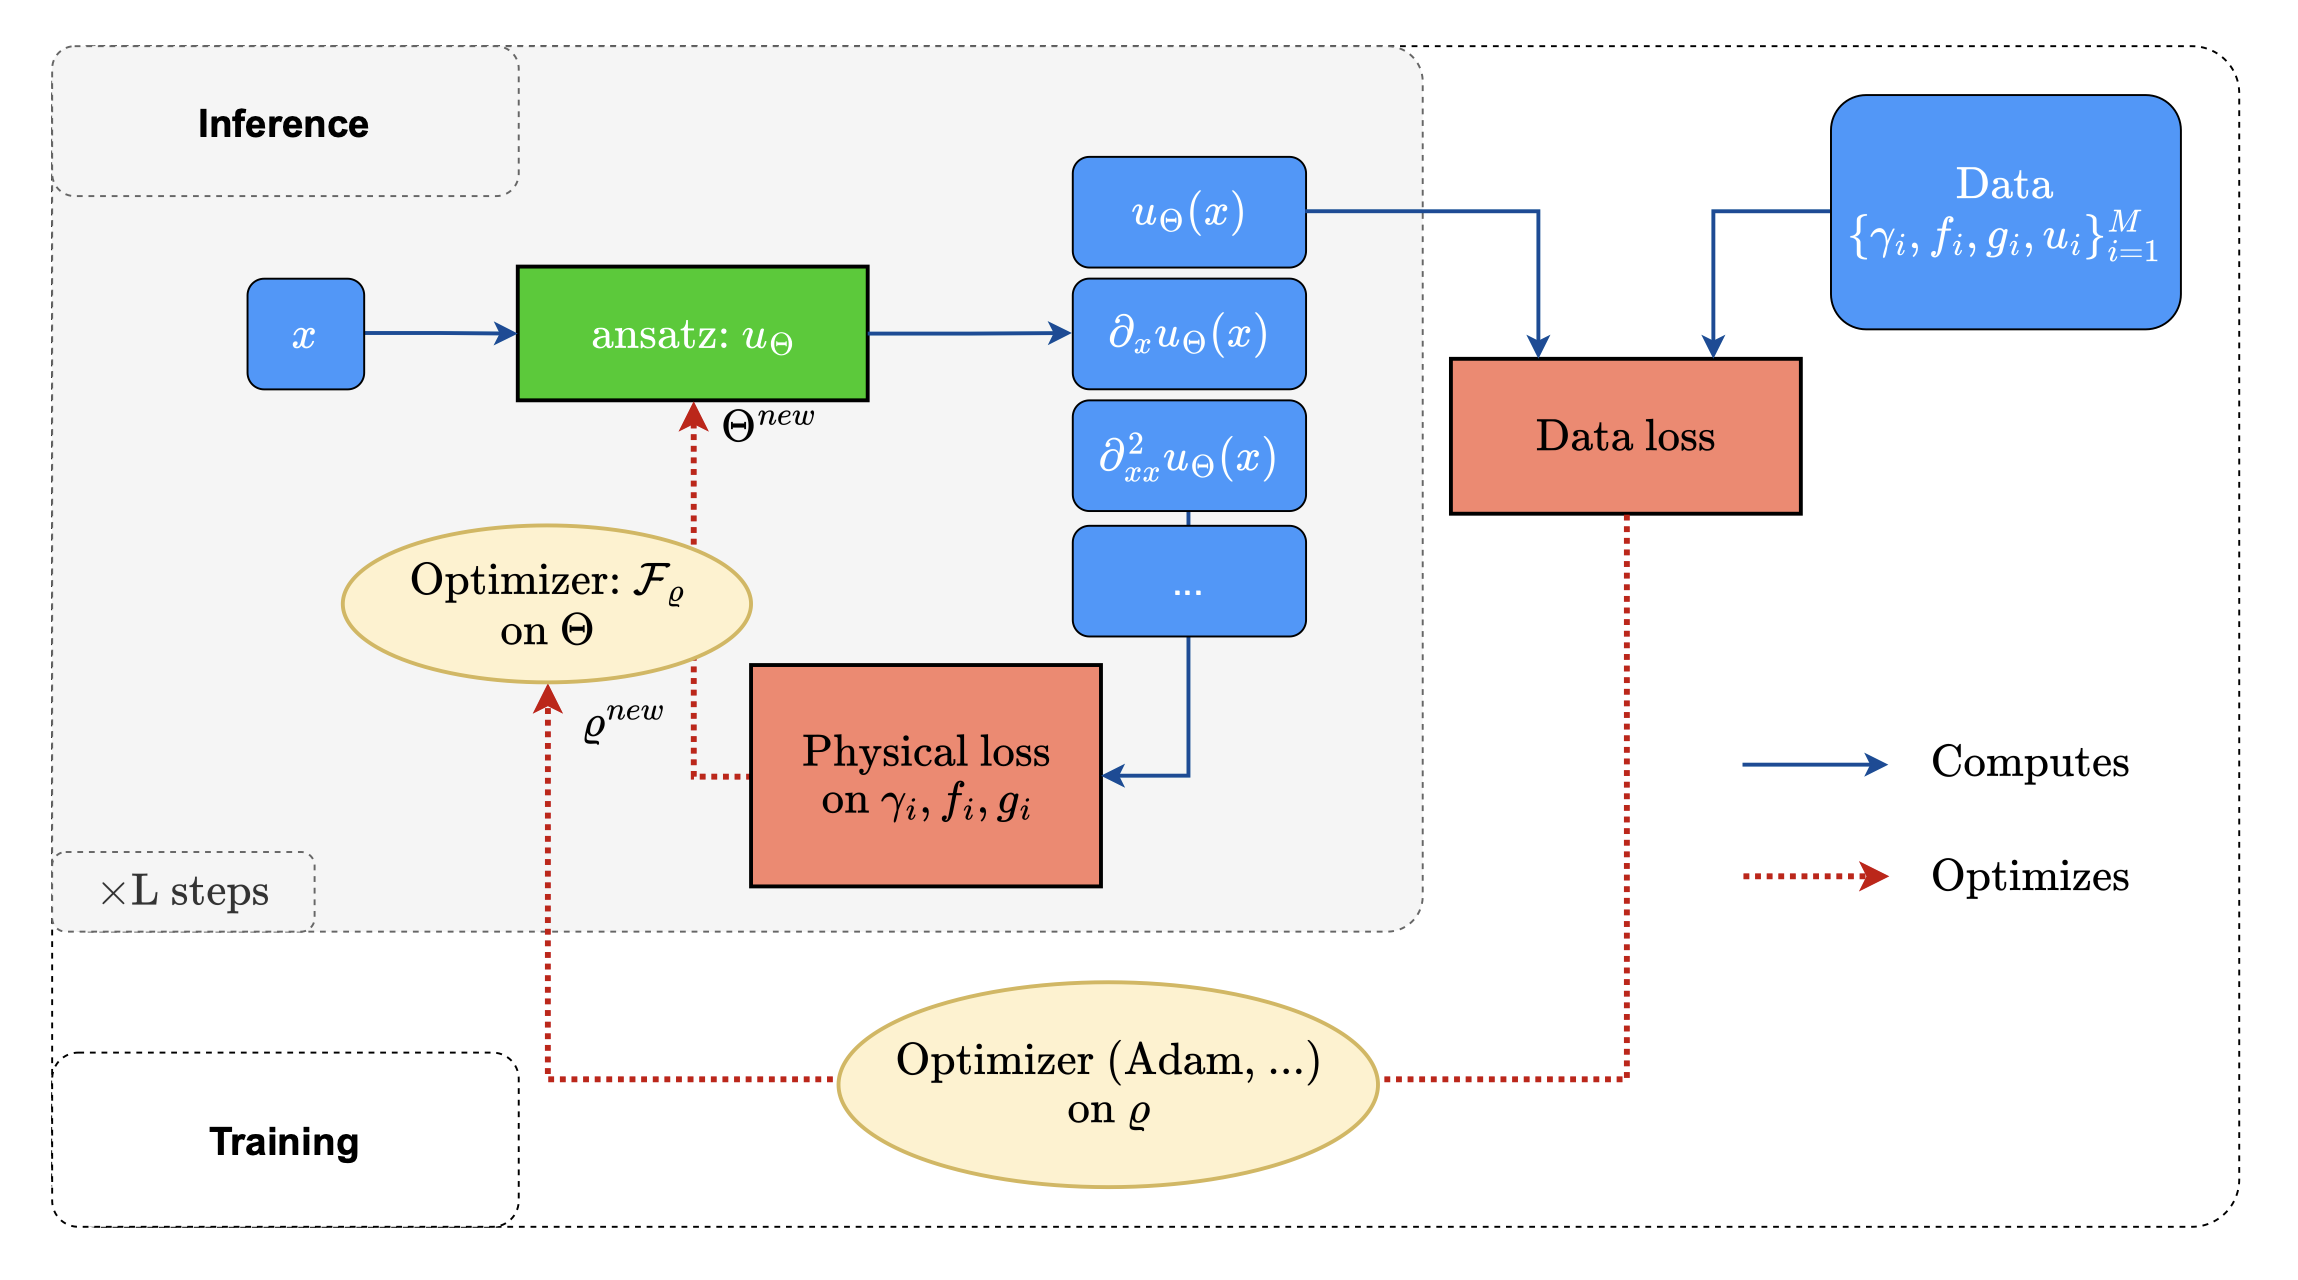
Physics-informed deep learning often faces optimization challenges due to the complexity of solving partial differential equations (PDEs), which involve exploring large solution spaces, require numerous iterations, and can lead to unstable training. These challenges arise particularly from the ill-conditioning of the optimization problem, caused by the differential terms in the loss function. To address these issues, we propose learning a solver, i.e., solving PDEs using a physics-informed iterative algorithm trained on data. Our method learns to condition a gradient descent algorithm that automatically adapts to each PDE instance, significantly accelerating and stabilizing the optimization process and enabling faster convergence of physics-aware models. Furthermore, while traditional physics-informed methods solve for a single PDE instance, our approach addresses parametric PDEs. Specifically, our method integrates the physical loss gradient with the PDE parameters to solve over a distribution of PDE parameters, including coefficients, initial conditions, or boundary conditions. We demonstrate the effectiveness of our method through empirical experiments on multiple datasets, comparing training and test-time optimization performance.
@inproceedings{leboudec2025learning,
  title = {Learning a Neural Solver for Parametric {PDE} to Enhance Physics-Informed Methods},
  author = {{Le Boudec}, Lise and {de Bézenac}, Emmanuel and Serrano, Louis and Regueiro Espiño, Ramón Daniel and Yin, Yuan and Gallinari, Patrick},
  booktitle = {The Thirteenth International Conference on Learning Representations},
  year = {2025},
  month = may,
}


2024
- Conference NeurIPSGEPS: Boosting Generalization in Parametric PDE Neural Solvers through Adaptive ConditioningIn The Thirty-eighth Annual Conference on Neural Information Processing Systems, Dec 2024
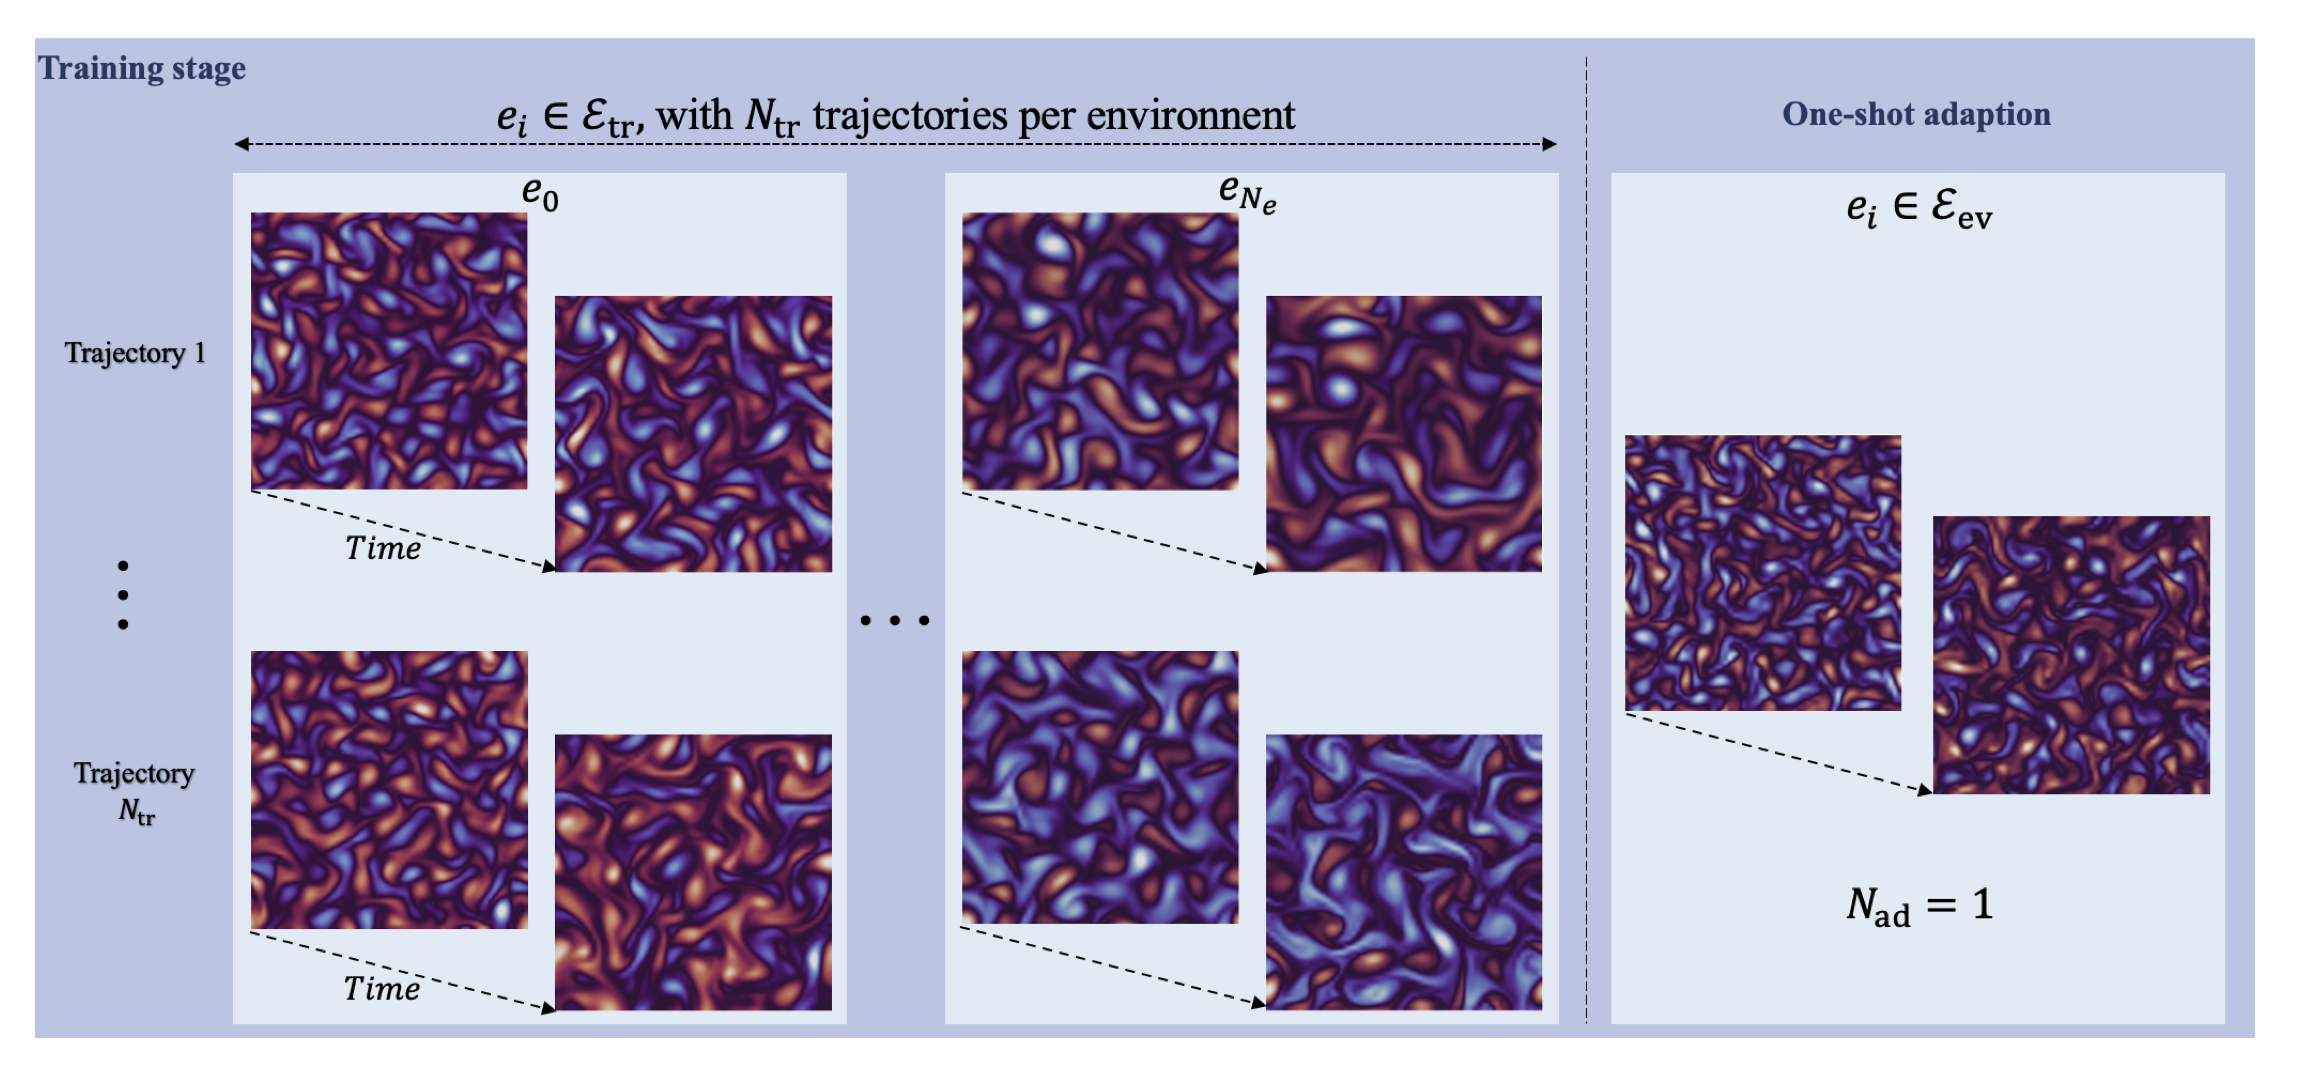
Solving parametric partial differential equations (PDEs) presents significant challenges for data-driven methods due to the sensitivity of spatio-temporal dynamics to variations in PDE parameters. Machine learning approaches often struggle to capture this variability. To address this, data-driven approaches learn parametric PDEs by sampling a very large variety of trajectories with varying PDE parameters. We first show that incorporating conditioning mechanisms for learning parametric PDEs is essential and that among them, adaptive conditioning, allows stronger generalization. As existing adaptive conditioning methods do not scale well with respect to the number of parameters to adapt in the neural solver, we propose GEPS, a simple adaptation mechanism to boost GEneralization in Pde Solvers via a first-order optimization and low-rank rapid adaptation of a small set of context parameters. We demonstrate the versatility of our approach for both fully data-driven and for physics-aware neural solvers. Validation performed on a whole range of spatio-temporal forecasting problems demonstrates excellent performance for generalizing to unseen conditions including initial conditions, PDE coefficients, forcing terms and solution domain.
@inproceedings{koupai2024learn, title = {GEPS: Boosting Generalization in Parametric {PDE} Neural Solvers through Adaptive Conditioning}, author = {{Kassaï Koupaï}, Armand and {Mifsut Benet}, Jorge and Yin, Yuan and Vittaut, Jean-Noël and Gallinari, Patrick}, booktitle = {The Thirty-eighth Annual Conference on Neural Information Processing Systems}, year = {2024}, month = dec, } - Workshop ECCV W-CODAReGentS: Real-World Safety-Critical Driving Scenario Generation Made StableIn ECCV 2024 Workshop on Multimodal Perception and Comprehension of Corner Cases in Autonomous Driving, Sep 2024
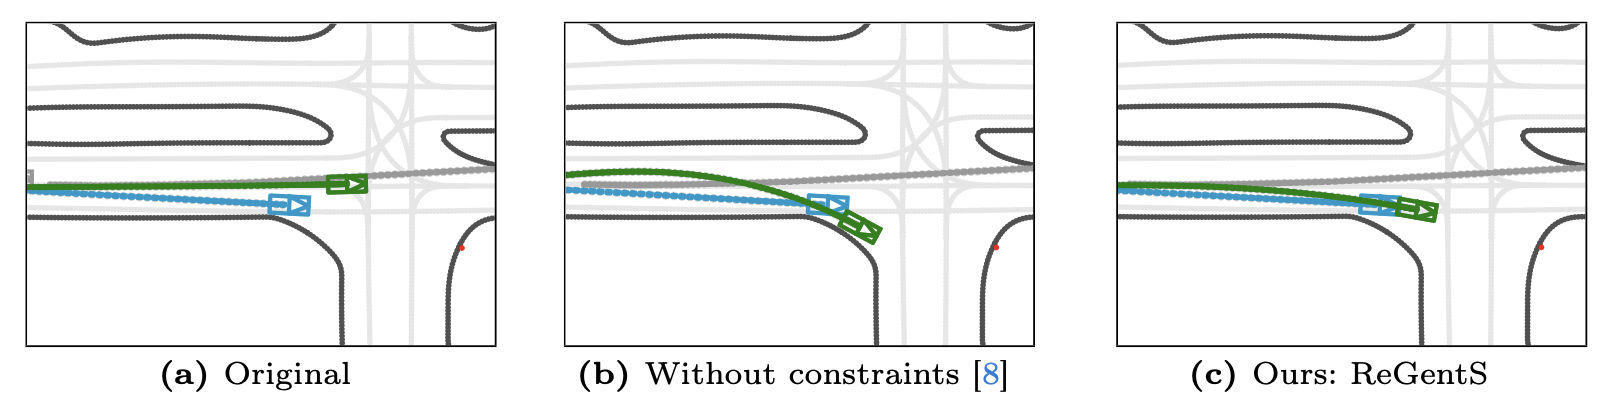
Machine learning based autonomous driving systems often face challenges with safety-critical scenarios that are rare in real-world data, hindering their large-scale deployment. While increasing real-world training data coverage could address this issue, it is costly and dangerous. This work explores generating safety-critical driving scenarios by modifying complex real-world regular scenarios through trajectory optimization. We propose ReGentS, which stabilizes generated trajectories and introduces heuristics to avoid obvious collisions and optimization problems. Our approach addresses unrealistic diverging trajectories and unavoidable collision scenarios that are not useful for training robust planner. We also extend the scenario generation framework to handle real-world data with up to 32 agents. Additionally, by using a differentiable simulator, our approach simplifies gradient descent-based optimization involving a simulator, paving the way for future advancements.
@inproceedings{yin2024regents, title = {ReGentS: Real-World Safety-Critical Driving Scenario Generation Made Stable}, author = {Yin, Yuan and Khayatan, Pegah and Zablocki, Éloi and Boulch, Alexandre and Cord, Matthieu}, booktitle = {ECCV 2024 Workshop on Multimodal Perception and Comprehension of Corner Cases in Autonomous Driving}, year = {2024}, month = sep, } - Journal TMLRTime Series Continuous Modeling for Imputation and Forecasting with Implicit Neural RepresentationsÉtienne Le Naour, Louis Serrano, Léon Migus, Yuan Yin, Ghislain Agoua, Nicolas Baskiotis, Patrick Gallinari, and Vincent GuigueTransactions on Machine Learning Research, Apr 2024
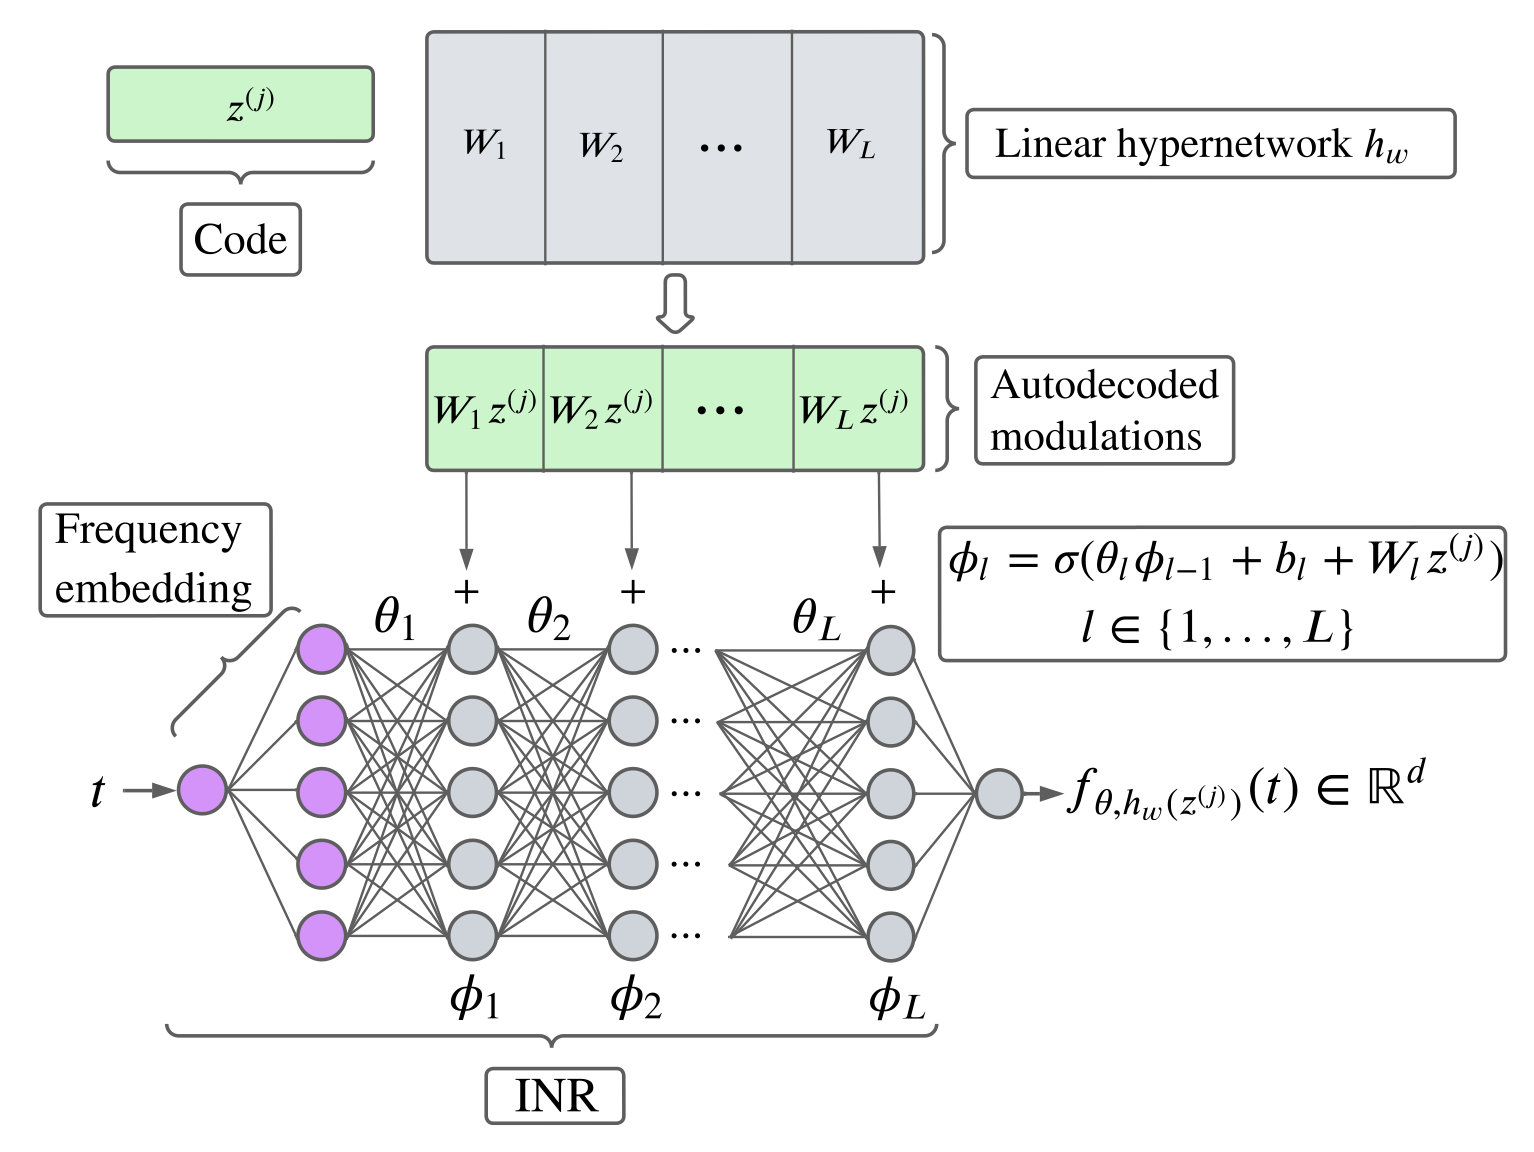
We introduce a novel modeling approach for time series imputation and forecasting, tailored to address the challenges often encountered in real-world data, such as irregular samples, missing data, or unaligned measurements from multiple sensors. Our method relies on a continuous-time-dependent model of the series’ evolution dynamics. It leverages adaptations of conditional, implicit neural representations for sequential data. A modulation mechanism, driven by a meta-learning algorithm, allows adaptation to unseen samples and extrapolation beyond observed time-windows for long-term predictions. The model provides a highly flexible and unified framework for imputation and forecasting tasks across a wide range of challenging scenarios. It achieves state-of-the-art performance on classical benchmarks and outperforms alternative time-continuous models.
@article{DBLP:journals/corr/abs-2306-05880,
  author = {Le Naour, Étienne and Serrano, Louis and Migus, Léon and Yin, Yuan and Agoua, Ghislain and Baskiotis, Nicolas and Gallinari, Patrick and Guigue, Vincent},
  title = {Time Series Continuous Modeling for Imputation and Forecasting with
                    Implicit Neural Representations},
  journal = {Transactions on Machine Learning Research},
  year = {2024},
  month = apr,
}


2023
- Thesis PhDPhysics-Aware Deep Learning and Dynamical Systems: Hybrid Modeling and Generalization. (Apprentissage profond pour la physique et les systèmes dynamiques : modélisation hybride et généralisation)Yuan YinSorbonne University, Paris, France, Jun 2023
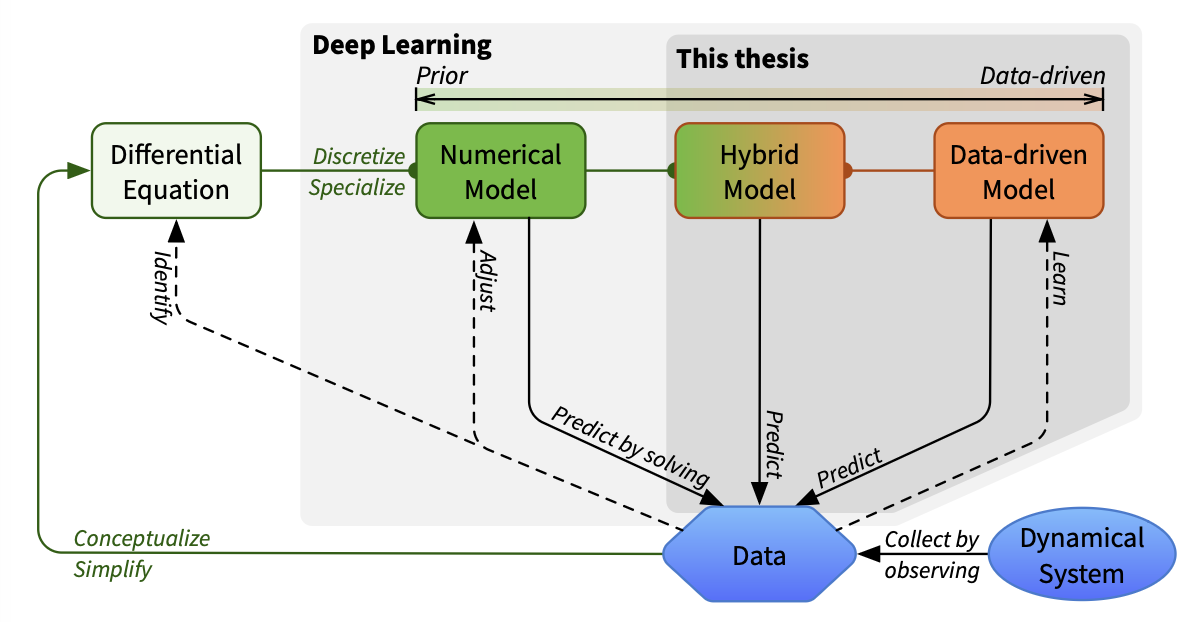
Yuan Yin received the Accessit to the AFIA IA 2024 Thesis Prize for his PhD thesis “Physics-Aware Deep Learning and Dynamical Systems: Hybrid Modeling and Generalization” supervised by Patrick Gallinari. See https://afia.asso.fr/le-prix-de-these-afia/.
Deep learning has made significant progress in various fields and has emerged as a promising tool for modeling physical dynamical phenomena that exhibit highly nonlinear relationships. However, existing approaches are limited in their ability to make physically sound predictions due to the lack of prior knowledge and to handle real-world scenarios where data comes from multiple dynamics or is irregularly distributed in time and space. This thesis aims to overcome these limitations in the following directions: improving neural network-based dynamics modeling by leveraging physical models through hybrid modeling; extending the generalization power of dynamics models by learning commonalities from data of different dynamics to extrapolate to unseen systems; and handling free-form data and continuously predicting phenomena in time and space through continuous modeling. We highlight the versatility of deep learning techniques, and the proposed directions show promise for improving their accuracy and generalization power, paving the way for future research in new applications.
@phdthesis{DBLP:phd/hal/Yin23, author = {Yin, Yuan}, title = {Physics-Aware Deep Learning and Dynamical Systems: Hybrid Modeling and Generalization. (Apprentissage profond pour la physique et les syst{\`{e}}mes dynamiques : mod{\'{e}}lisation hybride et g{\'{e}}n{\'{e}}ralisation)}, school = {Sorbonne University, Paris, France}, year = {2023}, month = jun, } - Conference ICLRContinuous PDE Dynamics Forecasting with Implicit Neural RepresentationsIn The Eleventh International Conference on Learning Representations, May 2023
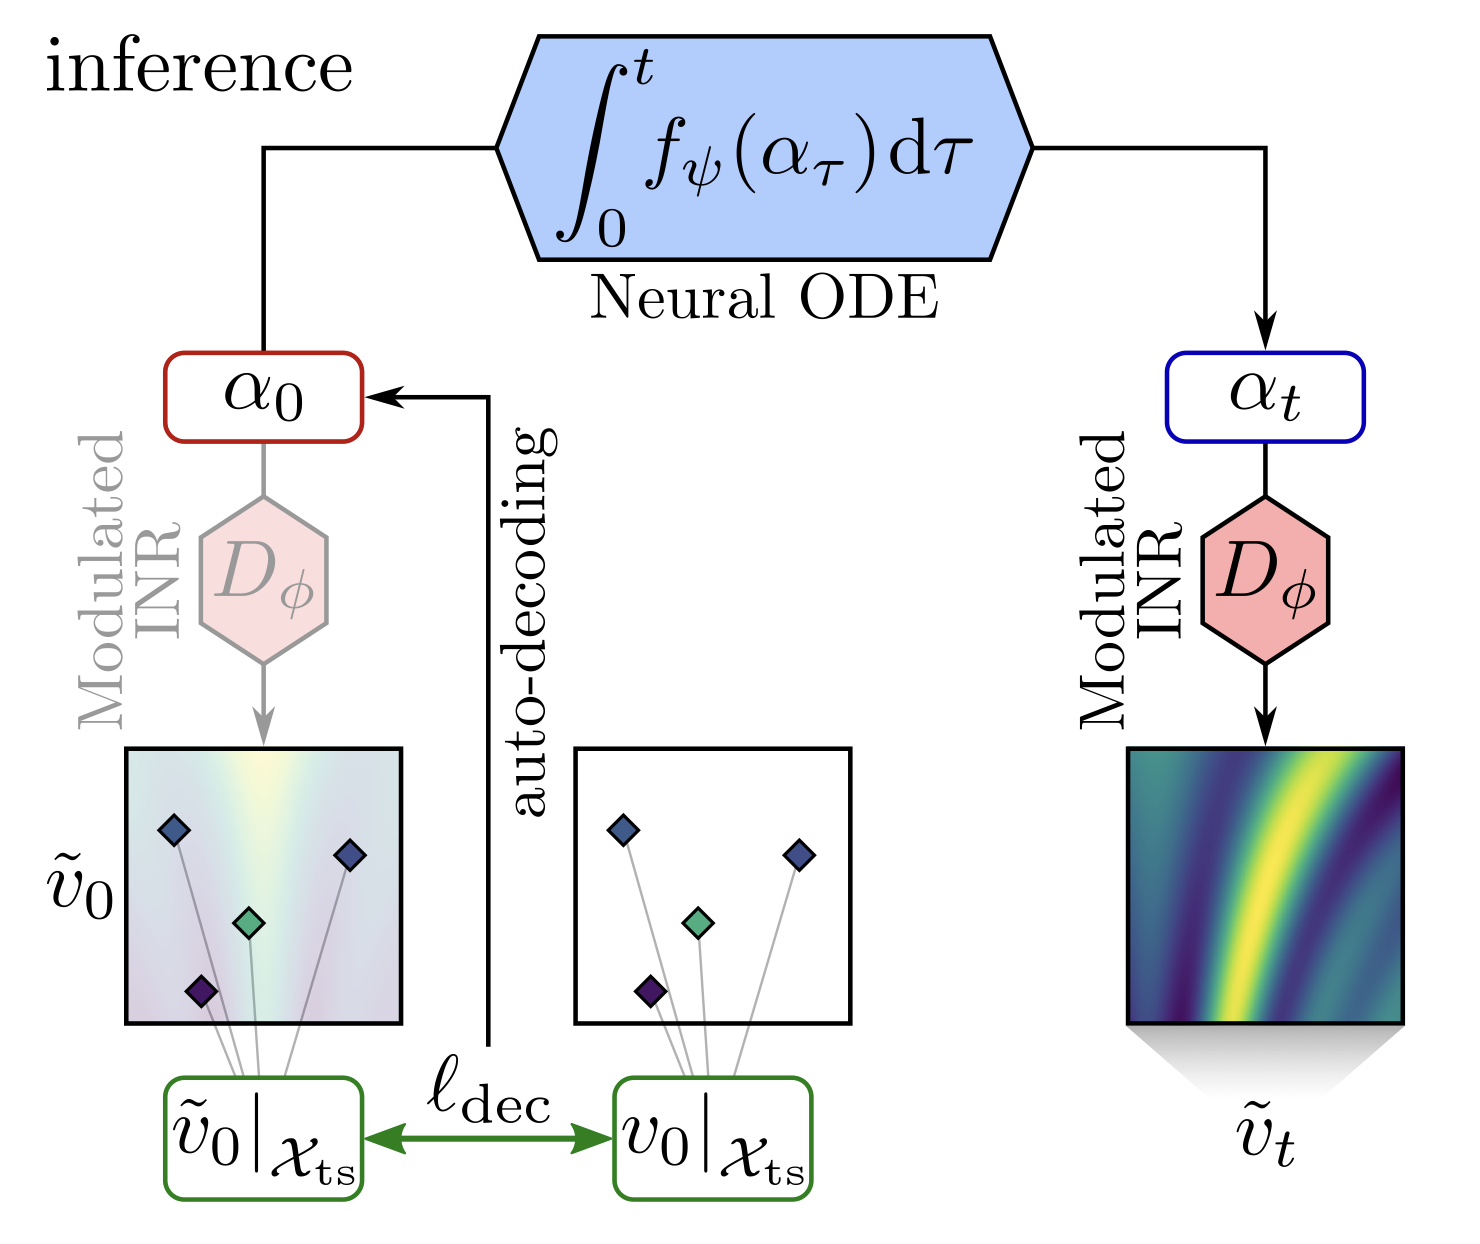
Effective data-driven PDE forecasting methods often rely on fixed spatial and / or temporal discretizations. This raises limitations in real-world applications like weather prediction where flexible extrapolation at arbitrary spatiotemporal locations is required. We address this problem by introducing a new data-driven approach, DINo, that models a PDE’s flow with continuous-time dynamics of spatially continuous functions. This is achieved by embedding spatial observations independently of their discretization via Implicit Neural Representations in a small latent space temporally driven by a learned ODE. This separate and flexible treatment of time and space makes DINo the first data-driven model to combine the following advantages. It extrapolates at arbitrary spatial and temporal locations; it can learn from sparse irregular grids or manifolds; at test time, it generalizes to new grids or resolutions. DINo outperforms alternative neural PDE forecasters in a variety of challenging generalization scenarios on representative PDE systems.
@inproceedings{YinKFRG2022, author = {Yin, Yuan and Kirchmeyer, Matthieu and Franceschi, Jean-Yves and Rakotomamonjy, Alain and Gallinari, Patrick}, title = {Continuous {PDE} Dynamics Forecasting with Implicit Neural Representations}, booktitle = {The Eleventh International Conference on Learning Representations}, publisher = {OpenReview.net}, month = may, year = {2023} } - Conference NeurIPSOperator Learning with Neural Fields: Tackling PDEs on General GeometriesLouis Serrano, Lise Le Boudec, Armand Kassaï Koupaï, Thomas X. Wang, Yuan Yin, Jean-Noël Vittaut, and Patrick GallinariIn Advances in Neural Information Processing Systems, Dec 2023
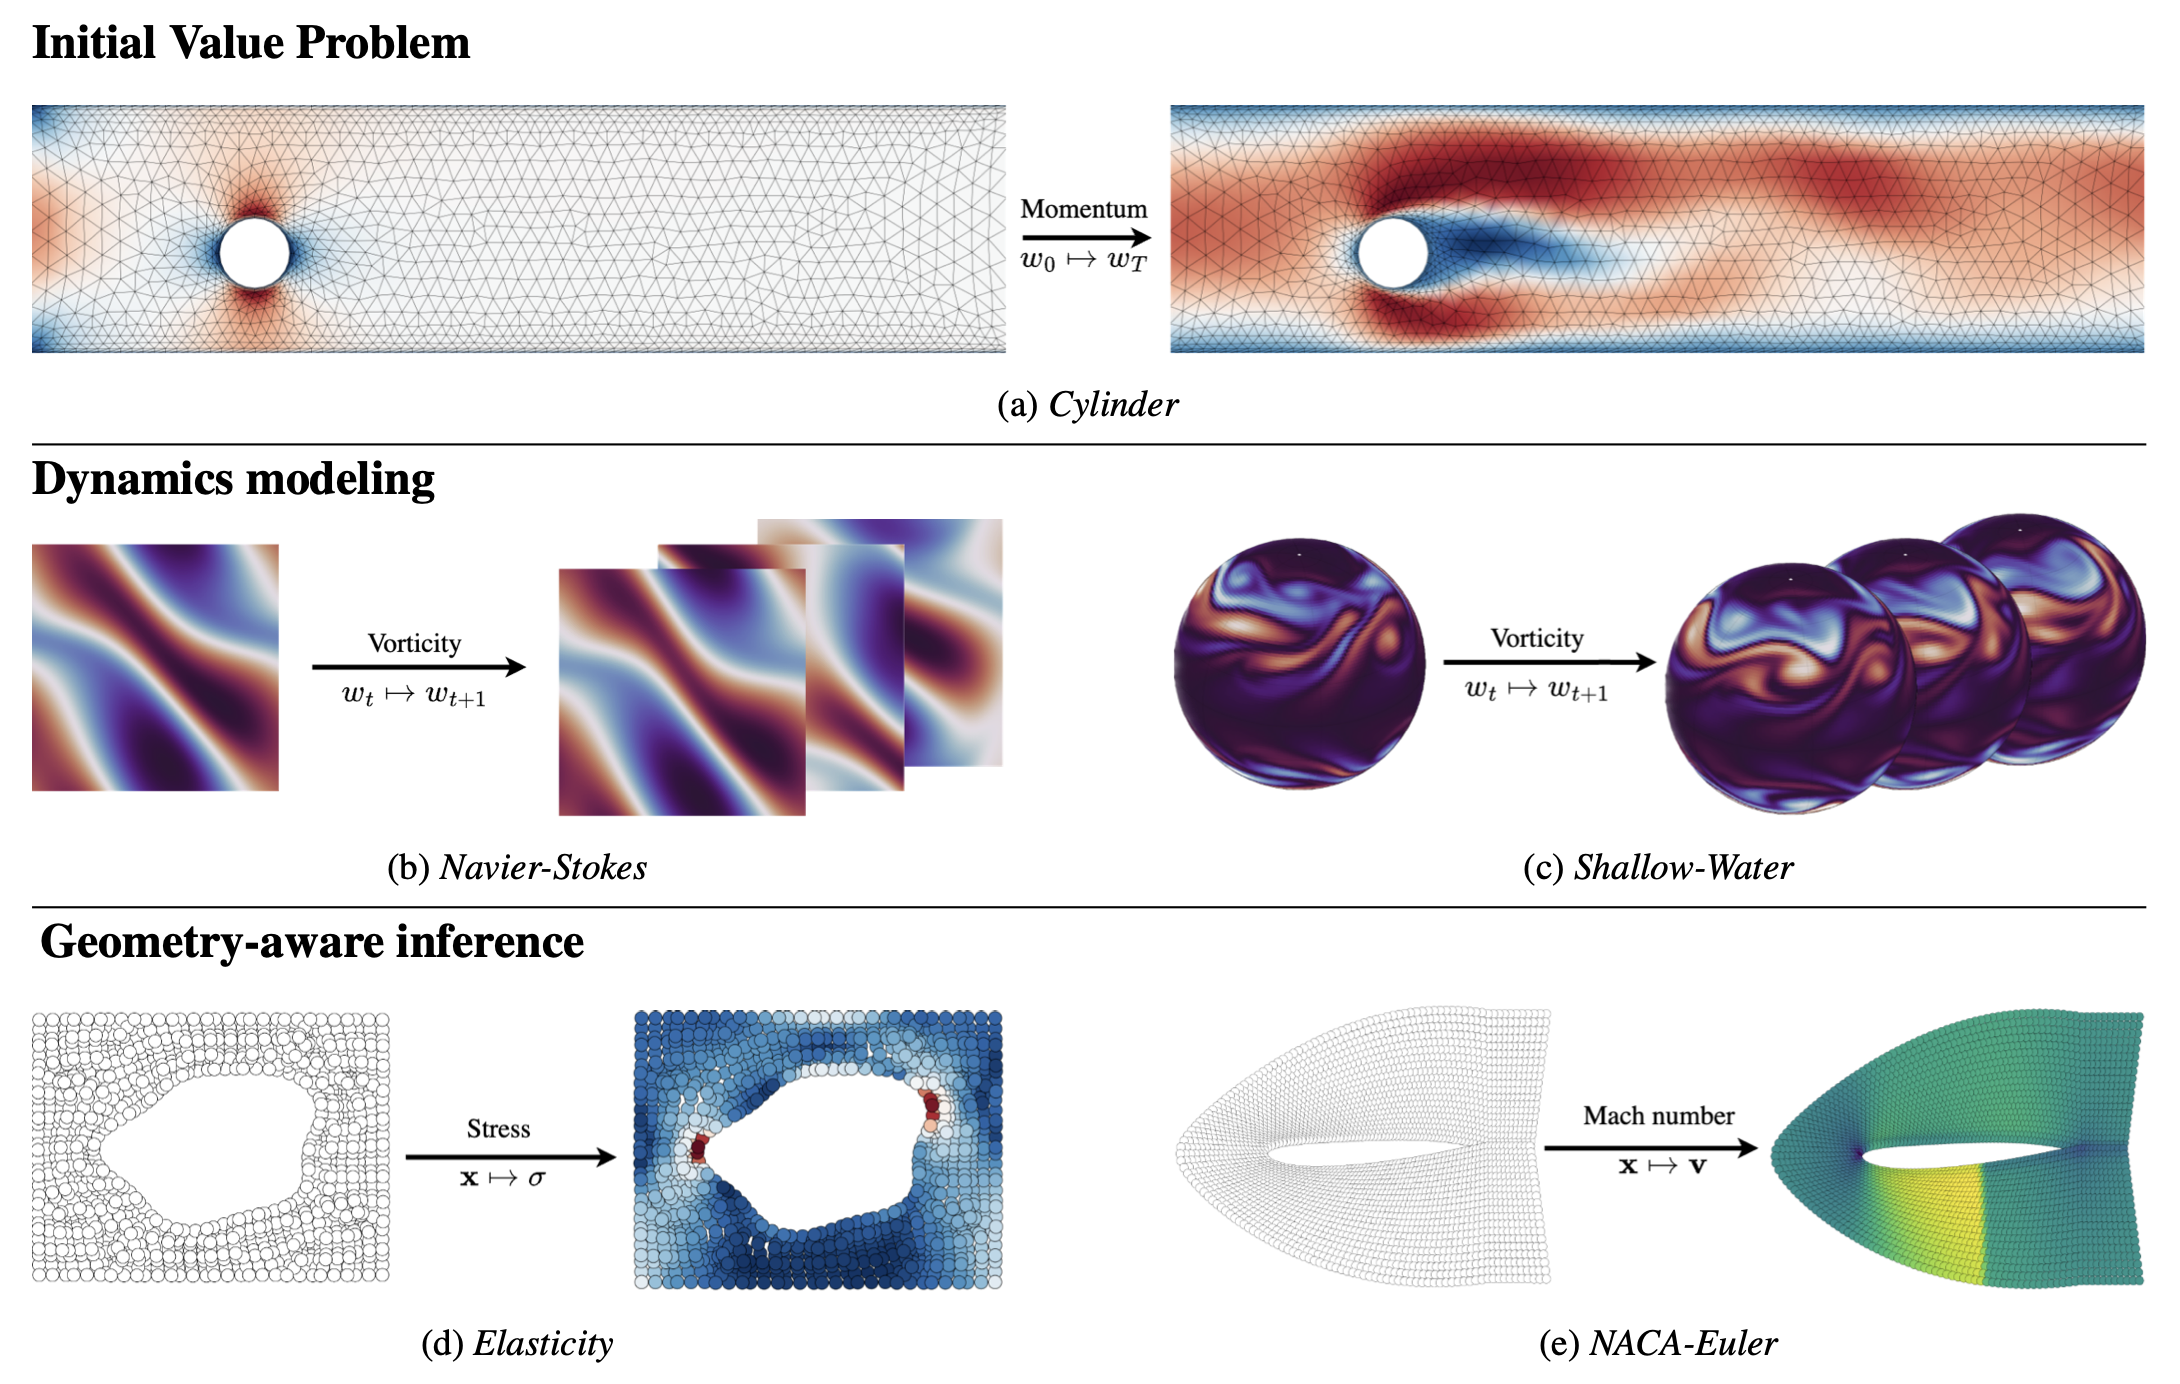
Machine learning approaches for solving partial differential equations require learning mappings between function spaces. While convolutional or graph neural networks are constrained to discretized functions, neural operators present a promising milestone toward mapping functions directly. Despite impressive results they still face challenges with respect to the domain geometry and typically rely on some form of discretization. In order to alleviate such limitations, we present CORAL, a new method that leverages coordinate-based networks for solving PDEs on general geometries. CORAL is designed to remove constraints on the input mesh, making it applicable to any spatial sampling and geometry. Its ability extends to diverse problem domains, including PDE solving, spatio-temporal forecasting, and inverse problems like geometric design. CORAL demonstrates robust performance across multiple resolutions and performs well in both convex and non-convex domains, surpassing or performing on par with state-of-the-art models.
@inproceedings{serrano2023operator, title = {Operator Learning with Neural Fields: Tackling {PDE}s on General Geometries}, author = {Serrano, Louis and {Le Boudec}, Lise and {Kassaï Koupaï}, Armand and Wang, Thomas X. and Yin, Yuan and Vittaut, Jean-Noël and Gallinari, Patrick}, booktitle = {Advances in Neural Information Processing Systems}, year = {2023}, month = dec, } - Workshop ICML SynS&MLINFINITY: Neural Field Modeling for Reynolds-Averaged Navier-Stokes EquationsIn ICML 2023 Workshop on Synergy of Scientific and Machine Learning Modeling, Jul 2023

For numerical design, the development of efficient and accurate surrogate models is paramount. They allow us to approximate complex physical phenomena, thereby reducing the computational burden of direct numerical simulations. We propose INFINITY, a deep learning model that utilizes implicit neural representations (INRs) to address this challenge. Our framework encodes geometric information and physical fields into compact representations and learns a mapping between them to infer the physical fields. We use an airfoil design optimization problem as an example task and we evaluate our approach on the challenging AirfRANS dataset, which closely resembles real-world industrial use-cases. The experimental results demonstrate that our framework achieves state-of-the-art performance by accurately inferring physical fields throughout the volume and surface. Additionally we demonstrate its applicability in contexts such as design exploration and shape optimization: our model can correctly predict drag and lift coefficients while adhering to the equations.
@inproceedings{serranoMYMG2023, title = {INFINITY: Neural Field Modeling for Reynolds-Averaged Navier-Stokes Equations}, author = {Serrano, Louis and Migus, Léon and Yin, Yuan and Mazari, Jocelyn Ahmed and Gallinari, Patrick}, url = {https://hal.science/hal-04171439}, booktitle = {{ICML 2023 Workshop on Synergy of Scientific and Machine Learning Modeling}}, address = {Honolulu, HI, United States}, year = {2023}, month = jul, } - Journal JDSAImproving Trust and Confidence in Medical Skin Lesion Diagnosis Through Explainable Deep LearningCarlo Metta, Andrea Beretta, Riccardo Guidotti, Yuan Yin, Patrick Gallinari, Salvatore Rinzivillo, and Fosca GiannottiInternational Journal of Data Science and Analytics, Jun 2023
A key issue in critical contexts such as medical diagnosis is the interpretability of the deep learning models adopted in decision-making systems. Research in eXplainable Artificial Intelligence (XAI) is trying to solve this issue. However, often XAI approaches are only tested on generalist classifier and do not represent realistic problems such as those of medical diagnosis. In this paper, we aim at improving the trust and confidence of users towards automatic AI decision systems in the field of medical skin lesion diagnosis by customizing an existing XAI approach for explaining an AI model able to recognize different types of skin lesions. The explanation is generated through the use of synthetic exemplar and counter-exemplar images of skin lesions and our contribution offers the practitioner a way to highlight the crucial traits responsible for the classification decision. A validation survey with domain experts, beginners, and unskilled people shows that the use of explanations improves trust and confidence in the automatic decision system. Also, an analysis of the latent space adopted by the explainer unveils that some of the most frequent skin lesion classes are distinctly separated. This phenomenon may stem from the intrinsic characteristics of each class and may help resolve common misclassifications made by human experts.
@article{carlo2023,
  author = {Metta, Carlo and Beretta, Andrea and Guidotti, Riccardo and Yin, Yuan and Gallinari, Patrick and Rinzivillo, Salvatore and Giannotti, Fosca},
  isbn = {2364-4168},
  journal = {International Journal of Data Science and Analytics},
  title = {Improving Trust and Confidence in Medical Skin Lesion Diagnosis Through Explainable Deep Learning},
  year = {2023},
  month = jun,
}


2022
- Conference ICMLGeneralizing to New Physical Systems via Context-Informed Dynamics ModelMatthieu Kirchmeyer*, Yuan Yin*, Jérémie Donà, Nicolas Baskiotis, Alain Rakotomamonjy, and Patrick GallinariIn International Conference on Machine Learning, Jul 2022
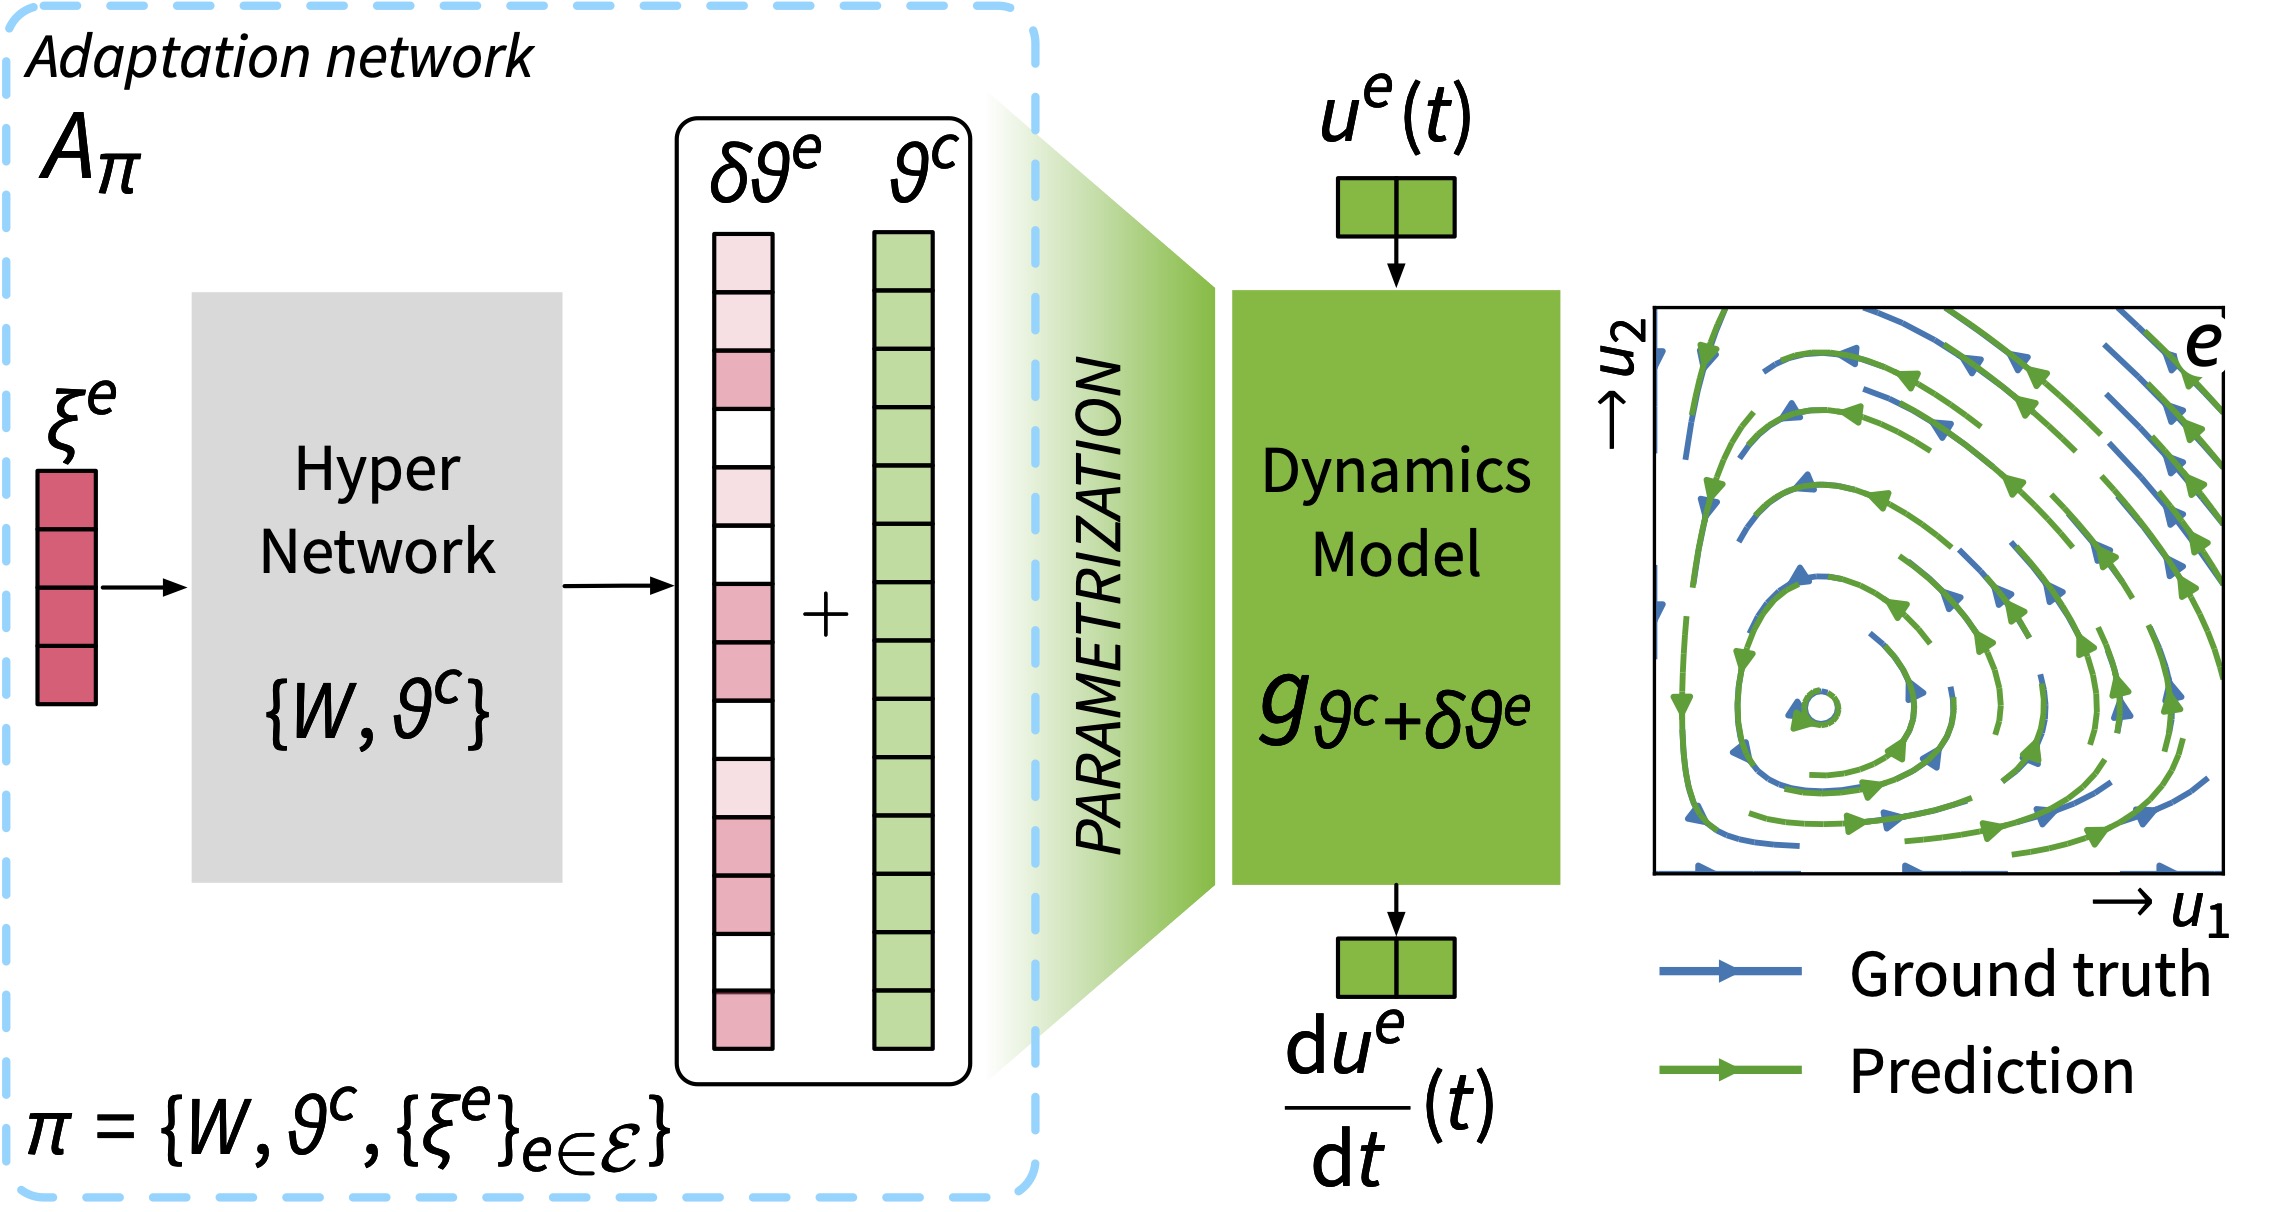
Data-driven approaches to modeling physical systems fail to generalize to unseen systems that share the same general dynamics with the learning domain, but correspond to different physical contexts. We propose a new framework for this key problem, context-informed dynamics adaptation (CoDA), which takes into account the distributional shift across systems for fast and efficient adaptation to new dynamics. CoDA leverages multiple environments, each associated to a different dynamic, and learns to condition the dynamics model on contextual parameters, specific to each environment. The conditioning is performed via a hypernetwork, learned jointly with a context vector from observed data. The proposed formulation constrains the search hypothesis space to foster fast adaptation and better generalization across environments. We theoretically motivate our approach and show state-of-the-art generalization results on a set of nonlinear dynamics, representative of a variety of application domains. We also show, on these systems, that new system parameters can be inferred from context vectors with minimal supervision.
@inproceedings{KirchmeyerYDBRG2022, author = {Kirchmeyer, Matthieu and Yin, Yuan and Donà, Jérémie and Baskiotis, Nicolas and Rakotomamonjy, Alain and Gallinari, Patrick}, booktitle = {International Conference on Machine Learning}, editor = {Chaudhuri, Kamalika and Jegelka, Stefanie and Song, Le and Szepesv{\'{a}}ri, Csaba and Niu, Gang and Sabato, Sivan}, pages = {11283--11301}, publisher = {{PMLR}}, series = {Proceedings of Machine Learning Research}, title = {Generalizing to New Physical Systems via Context-Informed Dynamics Model}, volume = {162}, year = {2022}, month = jul } - Workshop ICLR WSMulti-scale Physical Representations for Approximating PDE Solutions with Graph Neural OperatorsIn Proceedings of Topological, Algebraic, and Geometric Learning Workshops 2022, May 2022

Representing physical signals at different scales is among the most challenging problems in engineering. Several multi-scale modeling tools have been developed to describe physical systems governed by \emphPartial Differential Equations (PDEs). These tools are at the crossroad of principled physical models and numerical schema. Recently, data-driven models have been introduced to speed-up the approximation of PDE solutions compared to numerical solvers. Among these recent data-driven methods, neural integral operators are a class that learn a mapping between function spaces. These functions are discretized on graphs (meshes) which are appropriate for modeling interactions in physical phenomena. In this work, we study three multi-resolution schema with integral kernel operators that can be approximated with Message Passing Graph Neural Networks (MPGNNs). To validate our study, we make extensive MPGNNs experiments with well-chosen metrics considering steady and unsteady PDEs.
@inproceedings{Migus2022MultiscalePR,
  title = {Multi-scale Physical Representations for Approximating PDE Solutions with Graph Neural Operators },
  author = {Migus, Léon and Yin, Yuan and Mazari, Jocelyn Ahmed and Gallinari, Patrick},
  booktitle = {Proceedings of Topological, Algebraic, and Geometric Learning Workshops 2022},
  pages = {332--339},
  year = {2022},
  month = may,
  editor = {Cloninger, Alexander and Doster, Timothy and Emerson, Tegan and Kaul, Manohar and Ktena, Ira and Kvinge, Henry and Miolane, Nina and Rieck, Bastian and Tymochko, Sarah and Wolf, Guy},
  volume = {196},
  series = {Proceedings of Machine Learning Research},
  publisher = {PMLR},
}


2021
- Conference NeurIPSLEADS: Learning Dynamical Systems that Generalize Across EnvironmentsIn Advances in Neural Information Processing Systems, Dec 2021
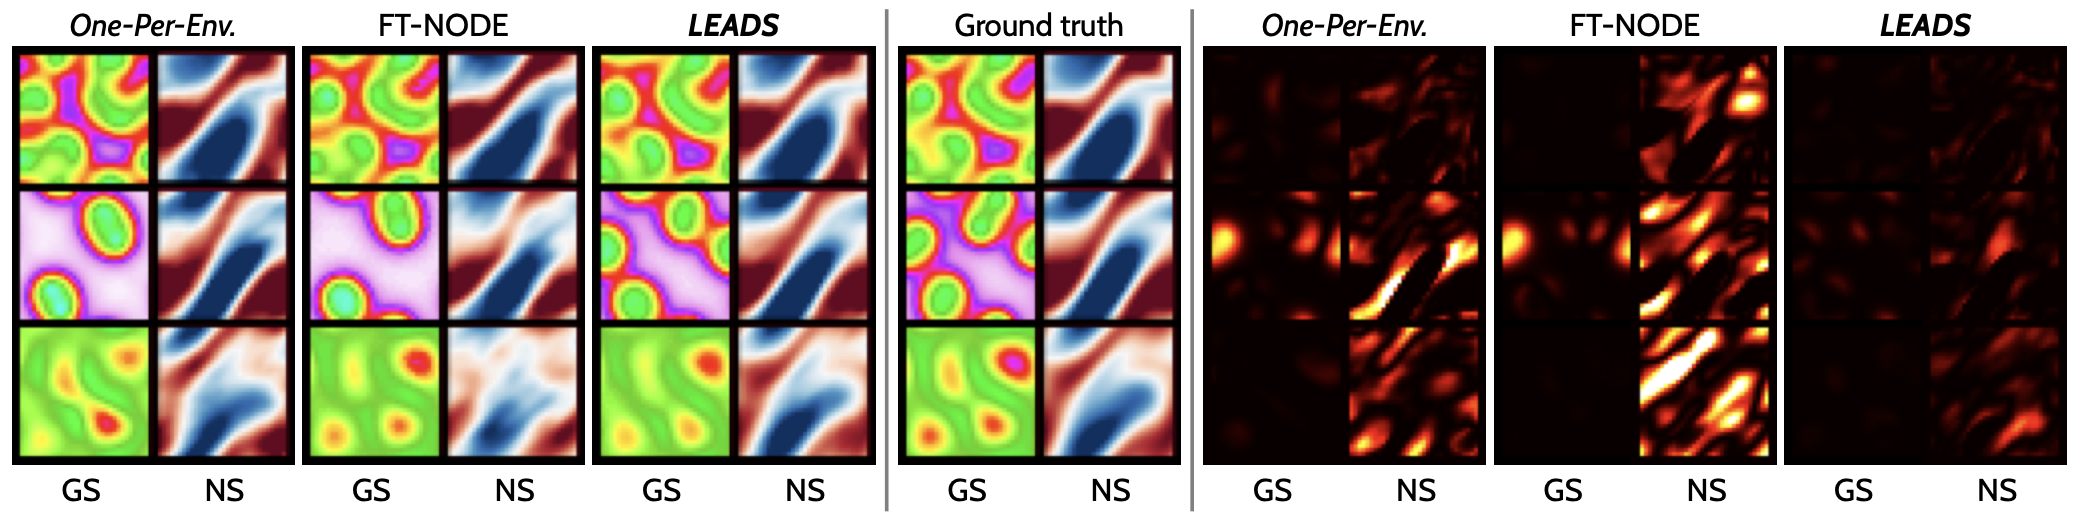
When modeling dynamical systems from real-world data samples, the distribution of data often changes according to the environment in which they are captured, and the dynamics of the system itself vary from one environment to another. Generalizing across environments thus challenges the conventional frameworks. The classical settings suggest either considering data as i.i.d. and learning a single model to cover all situations or learning environment-specific models. Both are sub-optimal: the former disregards the discrepancies between environments leading to biased solutions, while the latter does not exploit their potential commonalities and is prone to scarcity problems. We propose LEADS, a novel framework that leverages the commonalities and discrepancies among known environments to improve model generalization. This is achieved with a tailored training formulation aiming at capturing common dynamics within a shared model while additional terms capture environment-specific dynamics. We ground our approach in theory, exhibiting a decrease in sample complexity with our approach and corroborate these results empirically, instantiating it for linear dynamics. Moreover, we concretize this framework for neural networks and evaluate it experimentally on representative families of nonlinear dynamics. We show that this new setting can exploit knowledge extracted from environment-dependent data and improves generalization for both known and novel environments.
@inproceedings{Yin2021LEADS, author = {Yin, Yuan and Ayed, Ibrahim and {de Bézenac}, Emmanuel and Baskiotis, Nicolas and Gallinari, Patrick}, booktitle = {Advances in Neural Information Processing Systems}, editor = {Ranzato, Marc'Aurelio and Beygelzimer, Alina and Dauphin, Yann N. and Liang, Percy and Vaughan, Jennifer Wortman}, pages = {7561--7573}, title = {{LEADS:} Learning Dynamical Systems that Generalize Across Environments}, year = {2021}, month = dec } - Augmenting Physical Models with Deep Networks for Complex Dynamics ForecastingYuan Yin*, Vincent Le Guen*, Jérémie Donà*, Emmanuel de Bézenac*, Ibrahim Ayed*, Nicolas Thome, and Patrick GallinariIn 9th International Conference on Learning Representations, May 2021
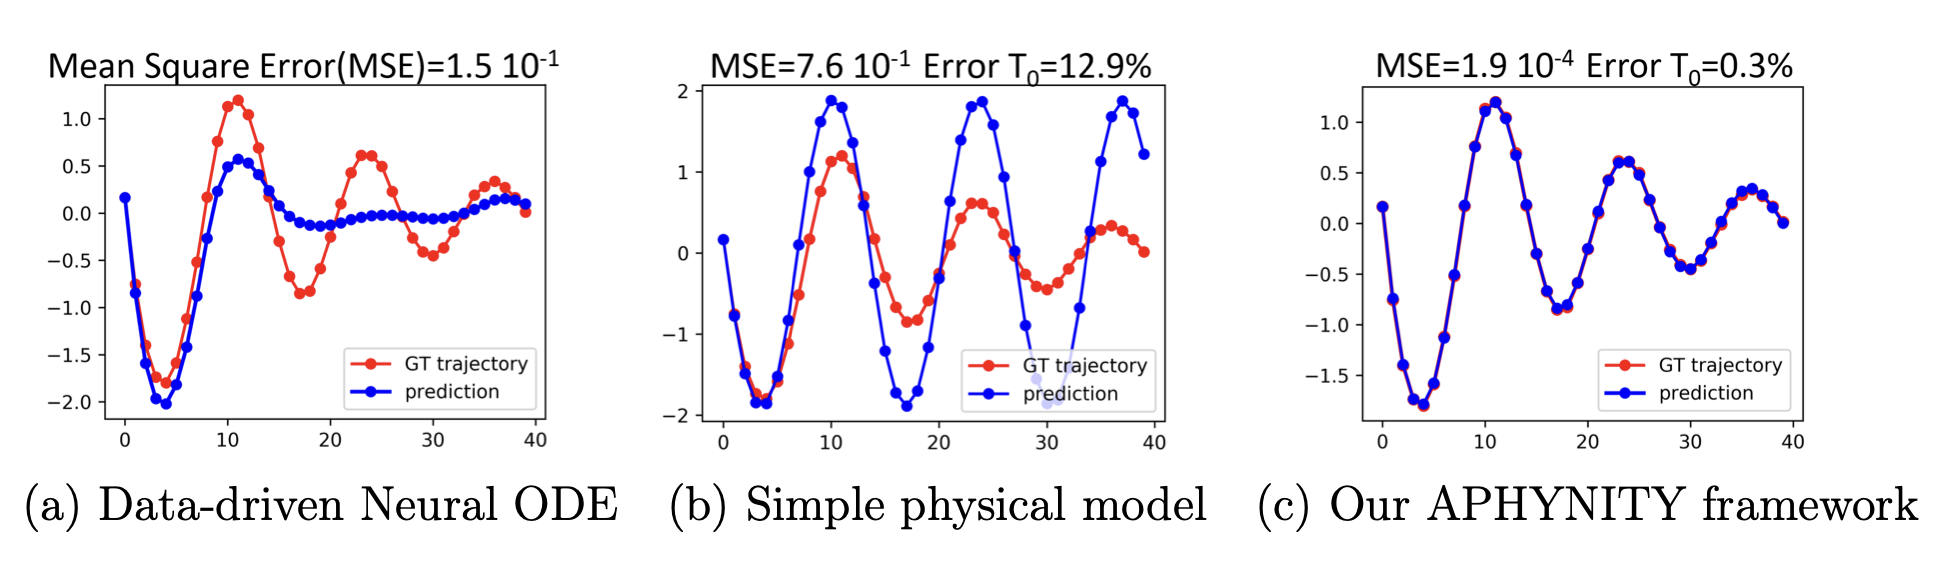
Forecasting complex dynamical phenomena in settings where only partial knowledge of their dynamics is available is a prevalent problem across various scientific fields. While purely data-driven approaches are arguably insufficient in this context, standard physical modeling based approaches tend to be over-simplistic, inducing non-negligible errors. In this work, we introduce the APHYNITY framework, a principled approach for augmenting incomplete physical dynamics described by differential equations with deep data-driven models. It consists in decomposing the dynamics into two components: a physical component accounting for the dynamics for which we have some prior knowledge, and a data-driven component accounting for errors of the physical model. The learning problem is carefully formulated such that the physical model explains as much of the data as possible, while the data-driven component only describes information that cannot be captured by the physical model, no more, no less. This not only provides the existence and uniqueness for this decomposition, but also ensures interpretability and benefits generalization. Experiments made on three important use cases, each representative of a different family of phenomena, i.e. reaction-diffusion equations, wave equations and the non-linear damped pendulum, show that APHYNITY can efficiently leverage approximate physical models to accurately forecast the evolution of the system and correctly identify relevant physical parameters.
@inproceedings{Yin2021Aphynity,
  author = {Yin, Yuan and Le Guen, Vincent and Donà, Jérémie and {de Bézenac}, Emmanuel and Ayed, Ibrahim and Thome, Nicolas and Gallinari, Patrick},
  booktitle = {9th International Conference on Learning Representations},
  publisher = {OpenReview.net},
  title = {Augmenting Physical Models with Deep Networks for Complex Dynamics Forecasting},
  year = {2021},
  month = may,
}


2020
- PreprintUnsupervised Spatiotemporal Data InpaintingSep 2020

We tackle the problem of inpainting occluded area in spatiotemporal sequences, such as cloud occluded satellite observations, in an unsupervised manner. We place ourselves in the setting where there is neither access to paired nor unpaired training data. We consider several cases in which the underlying information of the observed sequence in certain areas is lost through an observation operator. In this case, the only available information is provided by the observation of the sequence, the nature of the measurement process and its associated statistics. We propose an unsupervised-learning framework to retrieve the most probable sequence using a generative adversarial network. We demonstrate the capacity of our model to exhibit strong reconstruction capacity on several video datasets such as satellite sequences or natural videos.
@misc{yin2020unsupervised,
  author = {Yin, Yuan and Pajot, Arthur and {de Bézenac}, Emmanuel and Gallinari, Patrick},
  title = {Unsupervised Spatiotemporal Data Inpainting},
  year = {2020},
  month = sep,
}

2019
- Workshop CIUnsupervised Inpainting for Occluded Sea Surface Temperature SequencesIn Proceedings of the 9th International Workshop on Climate Informatics: CI 2019, Dec 2019

Sea Surface Temperature (SST) data remotely detected from satellites are inevitably occluded by clouds or rains. To learn the prior of SST data and complete the missing part, inpainting approaches in machine learning often require ground truth in the occluded area, which is not applicable for remote SST. In this paper, we propose an inpainting approach based on generative adversarial networks (GANs) for occluded SST. It is capable to complete the occluded area without any supervision on ground truth data of the occluded area. Our framework is evaluated on real SST data with simulated cloud masks.
@inproceedings{yin2019,
  author = {Yin, Yuan and Pajot, Arthur and {de Bézenac}, Emmanuel and Gallinari, Patrick},
  booktitle = {Proceedings of the 9th International Workshop on Climate Informatics: CI 2019},
  editor = {Brajard, Julien and Charantonis, Anastase and Chen, Chen and Runge, Jakob},
  title = {Unsupervised Inpainting for Occluded Sea Surface Temperature Sequences},
  year = {2019},
  month = dec,
}

2017
- Journal IVCLocal feature approach to dorsal hand vein recognition by Centroid-based Circular Key-point Grid and fine-grained matchingImage Vision Computing, Feb 2017

Due to the great progress made by local feature matching in both performance and robustness of dorsal hand vein recognition, this paper proposes a novel and effective approach for such an issue by improving two major steps of the SIFT-like framework, i.e. key-point detection and matching. For the former, a new key-point generation pattern, namely Centroid-based Circular Key-point Grid (CCKG), is presented, which efficiently localizes a certain number of points on the dorsal hand for the following SIFT feature extraction, leading to a discriminative description. In contrast to the existing key-point detectors, CCKG comprehensively accounts for the properties of the dorsal hand, including the vein network as well as the surrounding corium region, and hence achieves both good representativeness and low complexity. For the latter, a fine-grained matching process is introduced which makes use of Multi-task Sparse Representation Classifier (MtSRC). Compared with the traditional coarse-grained one that counts the number of associated SIFT features between the gallery and probe dorsal hand images, MtSRC precisely calculates the error of each feature of the probe as reconstructed by the gallery features, and all the errors of the probe features are combined for similarity measurement, reaching a better accuracy in recognition. The proposed approach is evaluated on the NCUT Part A database and shows its effectiveness in both the identification and verification scenarios. Additionally, the experimental results achieved on the NCUT Part B dataset highlight its generality and robustness to low quality images.
@article{DBLP:journals/ivc/HuangZYWW17,
  author = {Huang, Di and Zhang, Renke and Yin, Yuan and Wang, Yiding and Wang, Yunhong},
  title = {Local feature approach to dorsal hand vein recognition by Centroid-based
                    Circular Key-point Grid and fine-grained matching},
  journal = {Image Vision Computing},
  volume = {58},
  pages = {266--277},
  year = {2017},
  month = feb,
}

No publications match “”.